2. Kullback-Leibler divergence
The KL divergence evaluates the difference of two different distributions, It's often a powerful tool for make two distributions coincide in the training of deep-learning neural networks.
- Reading time
- 3 min
- Length
- 465 words
- Updated
- Sep 15, 2026
- Total views
- --
1. Definition
KL divergence is an important way to evaluate the similarity of 2 distributions, then give a reasonable Loss. Thus it is often used as the learning function of generated network, for example, VAE (Variational autoencoder)
(1) Concepts of KL-divergence
The Kullback-Leibler divergence(KL divergence)[1] is also called relative entropy or I-divergence, is a type of statistical or distribution distance. which can measure one distribution
or equivalent to :
Also it is expectation of the logarithmic difference between the probabilities
For continuous function, it is also called relative entropy (defined as integral):
Note
proof of positiveness of KL-divergence Using Jensen's inequality, we have, for a strict convex function :
Then we have :
(2) Design Thoughts of KL-divergence
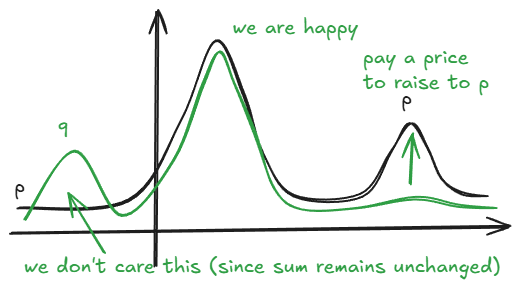
In the application purpose, we want the
Since we care more about the q is similar to p
Intuitively, there are three cases of importance[2] (changed some expressions for consistency): • If
(3) Code Implementation
The most common case is to compute the KL_divergence between two normal distributions. In that case, from (1.1)[3], we know :
For the first term, we have that :
Then for the second term :
So the final term reduce to :
def kl_divergence(
    mu1: torch.Tensor, logvar1: torch.Tensor,
    mu2: torch.Tensor, logvar2: torch.Tensor
):
    """
    :param mu1:
    :param logvar1:
    :param mu2:
    :param logvar2:
    :return:
    """
    fst_term = 1/2 * (logvar1 - logvar2)
    var1 = torch.exp(logvar1)
    var2 = torch.exp(logvar2)
    scd_term = 1/(2 * var2) * (var1 - var2 + (mu1 - mu2) ** 2)
return fst_term + scd_termWe note another version can be found as normal_kl function in topodiff [4], which has similar implementation, and reach the exact same results.
def normal_kl(mean1, logvar1, mean2, logvar2):
    """
    Compute the KL divergence between two gaussians.

    Shapes are automatically broadcasted, so batches can be compared to
    scalars, among other use cases.
    """
    tensor = None
    for obj in (mean1, logvar1, mean2, logvar2):
        if isinstance(obj, th.Tensor):
            tensor = obj
            break
    assert tensor is not None, "at least one argument must be a Tensor"

    # Force variances to be Tensors. Broadcasting helps convert scalars to
    # Tensors, but it does not work for th.exp().
    logvar1, logvar2 = [
        x if isinstance(x, th.Tensor) else th.tensor(x).to(tensor)
        for x in (logvar1, logvar2)
    ]

    return 0.5 * (
        -1.0
        + logvar2
        - logvar1
        + th.exp(logvar1 - logvar2)
        + ((mean1 - mean2) ** 2) * th.exp(-logvar2)
    )